Engineering My Website for the Agentic Web: How I Reached a 9.45 WebMCP Rate

Why designing for AI agents is the new responsive web design, how I built deterministic WebMCP tooling into my website, and why continuous CI testing matters.
A few weeks ago, I ran an experiment. I asked an autonomous AI agent to visit my personal website, find my executive background, check my speaking availability, and send me a short note.
The result was a mess.
The agent spent forty-five seconds downloading megabytes of compiled JavaScript chunks. It tried to parse my navigation header, got confused by an interactive React state toggle, guessed the CSS selector for my contact form, and ultimately crashed when my Cloudflare security rules flagged its headless browser headers as suspicious bot traffic.
That experiment was a wake-up call.
We are building powerful autonomous agents capable of reasoning through complex business problems, but the open web they navigate is still built entirely for human eyeballs. We expect agents to read rendered DOMs, click visual buttons, and scrape raw HTML. It is fragile, slow, and expensive.
I decided to re-engineer my entire website from the ground up to support the Model Context Protocol directly in the browser and on the server. Here is how I built it, how I reached a 9.45 out of 10.0 WebMCP readiness score, and why every engineering team needs to treat agent readiness as a first-class continuous integration requirement.
The New Responsive Design
In 2012, frontend engineering went through a fundamental shift called responsive web design. Before that, companies built desktop-only sites. When smartphones took over, those sites became unusable overnight. We had to rethink CSS media queries, fluid grids, and touch targets.
In 2026, we are at the exact same inflection point, but for autonomous agents.
When an AI agent visits your website today on behalf of a user, it should not have to parse visual layout trees or execute brittle Playwright scripts to interact with your business. It needs three things:
- Deterministic Discovery: An immediate, machine-readable declaration of who you are, what data you publish, and what actions you expose.
- Schema-Validated Tools: Callable endpoints with strict input validation so the agent can execute tasks without guessing.
- Frictionless Transport: Network paths that do not treat legitimate autonomous delegates as malicious DDoS bots.
This is what WebMCP (Web Model Context Protocol) provides—a standard rapidly gaining industry traction across hundreds of live domains indexed on The WebMCP Directory.
What I Built on zivisaiah.com
To turn my site into an agent-ready interface, I focused on four core layers.
1. Machine Discovery at the Root
I added a standardized discovery link in the HTML <head> pointing to a root manifest:
<link rel="webmcp-manifest" href="/webmcp-manifest.json" />
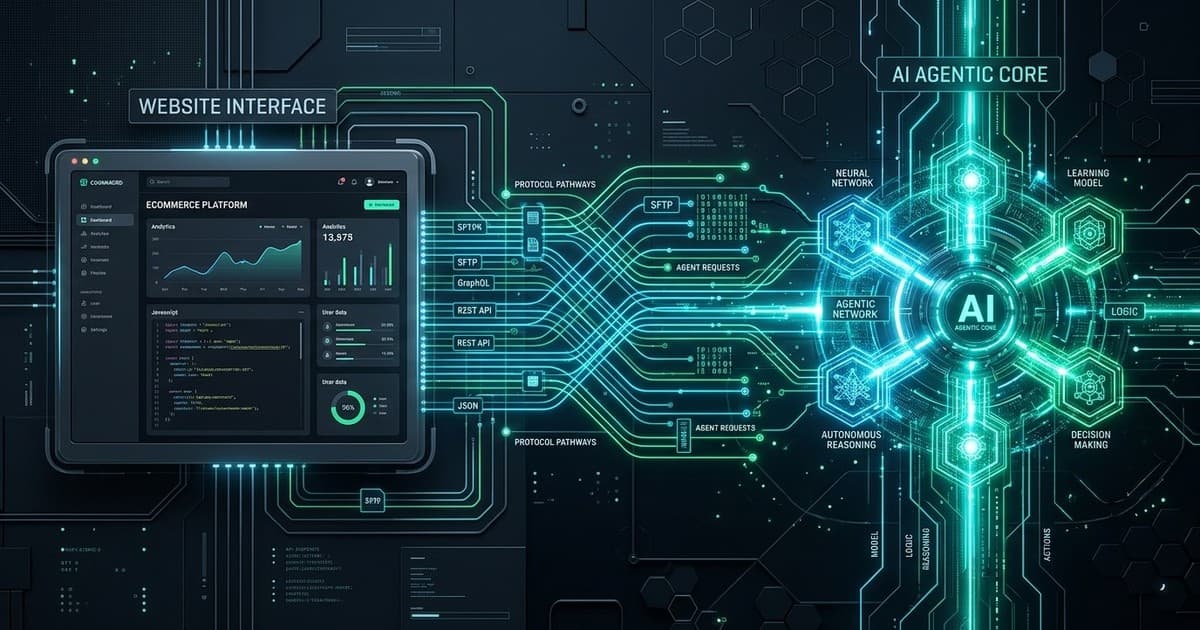
At /webmcp-manifest.json, my server exposes a clean JSON manifest defining available resources (such as my executive biography, project catalog, and live status) and callable tools (such as semantic essay search and direct inquiry dispatch).
Alongside the manifest, I maintain a curated /llms.txt and /llms-full.txt index. When an LLM crawler hits my domain, it gets clean markdown versions of all essays and career history without parsing navigation menus or footer links.
2. Deterministic Entity Semantics
Scrapers often hallucinate credentials because raw text lacks structured context. To fix this, I implemented an in-page JSON-LD @graph schema.
The schema explicitly binds my identity (Person with canonical LinkedIn, GitHub, and patent credentials) directly to the site (WebSite). When an agent queries who wrote an essay or checks my inventions, it reads structured data with zero ambiguity: 3 granted US patents and 1 pending in synthetic media defense and adaptive AI fraud prevention.
3. Server-Side Dynamic Tool Execution
Many sites make the mistake of creating static JSON dumps that quickly become outdated. On my site, every tool endpoint executes dynamically against live data:
GET /api/mcp/essays/search: Runs real-time keyword and category filtering directly over the markdown repository.POST /api/mcp/contact: Validates incoming agent payloads against a strict JSON Schema, enforces rate limits, logs inquiries securely, and dispatches notifications.GET /api/mcp/bio: Returns structured executive background and venture history.
Every endpoint returns explicit error codes and structured JSON, allowing an agent to handle edge cases gracefully.
4. Hardened Tool Security, Annotation Hints & Context Budgets
Opening up callable tools to autonomous agents introduces a real attack vector: indirect prompt injection. Because LLMs treat instructions, system prompts, and external data as a single continuous sequence of tokens, untrusted content returned by a web tool can hijack an agent's agency.
To secure my site’s tools against these failure modes, I aligned my endpoints with Google Chrome's official WebMCP tool security specifications:
- Annotation Hints (
readOnlyHint&untrustedContentHint): Idempotent read tools (such as essay search and executive bio retrieval) carryreadOnlyHint: true. This signals visiting agents that the operation is safe to auto-execute without prompting the human user for approval. Conversely, endpoints returning user-generated or third-party content carryuntrustedContentHint: true, instructing the agent to apply heightened scrutiny and sandboxing before acting on returned text. - Strict Character & Token Budgets: Autonomous agents have finite context windows and fragile attention mechanisms. Bloated JSON outputs trigger guardrails or blow past context budgets. I enforce tight constraints on every exposed tool: descriptions stay under 500 characters, parameter schemas under 150 characters, and tool responses under 1,500 characters (~375 tokens).
- Explicit Origin Isolation: In client-side WebMCP registrations (
document.modelContext.registerTool), tools remain strictly isolated to the host origin by default, requiring explicitexposedToallowlists before any cross-origin iframe can observe or invoke them.
5. WAF and CORS Tuning
Security rules often block automated user-agents by default. I configured open CORS headers (Access-Control-Allow-Origin: *) specifically on all WebMCP discovery and tool routes (/webmcp-manifest.json, /llms.txt, /api/mcp/*), while ensuring anti-bot heuristics distinguish legitimate client agents from malicious scrapers.
6. Inverted-Pyramid Answer Engine Optimization (AEO)
As search engines shift from classic blue links to generative synthesis (such as Google AI Overviews, Perplexity, and ChatGPT Search), discovering a website is no longer about keyword density: it is about providing direct, extractable answers.
To make my technical essays immediately consumable by generative engines, I implemented an inverted-pyramid content structure:
- Conversational Question Subheadings: Formatted as explicit questions that users and models ask (e.g.
## Why Does Browser Automation Fail for Autonomous Agents?). - The 40–60 Word Direct-Answer Snippet: Positioned immediately below each question heading is a self-contained, bold answer answering the question definitively with concrete data or metrics before expanding into deep narrative.
- Dual-Layer JSON-LD Schema: The site pairs
BlogPostingmetadata with dynamically extractedFAQPageandSpeakableschemas, ensuring generative crawlers can quote structured Q&A pairs without risking text mismatch penalties.
7. Mobile-First Responsive Information Architecture
A major challenge in technical publishing is presenting complex multi-dimensional comparisons without breaking mobile viewports.
On mobile screens (375px to 390px), traditional 3-column markdown tables compress into narrow 100px strips, forcing words to wrap onto single-letter vertical lines. To solve this, I retired dense multi-column tables in favor of Responsive Dimension Cards: structured, vertically-stacked comparison modules that render beautifully on phones with zero horizontal scrolling. Similarly, all in-body architectural schematics are authored in mobile-first vertical layouts and wrapped in interactive zoom links, allowing readers to tap and inspect high-resolution details cleanly.
Beyond WebMCP: OpenAPI 3.1, Manifest Stacks & Benchmarking with Ora
While WebMCP provides the browser runtime and client-side Model Context Protocol integration, preparing a domain for the broader agentic ecosystem requires a layered discovery stack.
Autonomous agents from different ecosystems look for distinct discovery markers:
- OpenAPI 3.1 Specification (
/openapi.json&/.well-known/openapi.json): Foundation models generating dynamic API clients require typed REST schemas for endpoints like/api/mcp/essays/searchand/api/mcp/contact. - Universal AI Plugin Manifest (
/.well-known/ai-plugin.json): Standard discovery manifest linking authentication type (none), documentation, and callable OpenAPI tool descriptions. - Tiered AI Crawler Architecture in
robots.txt: Ensuring legitimate agent crawlers have unambiguous access to root discovery paths. This requires separating three distinct classes of AI agents:- Foundational Pre-Training Crawlers: Preserving
CCBot(Common Crawl). Many engineering teams inadvertently disallow CCBot to reduce generic crawl bandwidth, but doing so blinds the open-source and frontier models (like LLaMA, Mistral, and DeepSeek) that rely on Common Crawl archives for their foundational training corpora. - Real-Time Answer Engines & Retrieval Agents: Providing full, unhindered access to
GPTBot,OAI-SearchBot,ChatGPT-User,ClaudeBot,[OraBot](https://ora.ai/),PerplexityBot, andDeepSeekBot. - Ecosystem-Specific Directives: Configuring explicit tokens like
Google-Extended(which controls training and grounding for Google Gemini and Vertex AI) andGoogleOther(Google R&D and automated fetchers), alongsideApplebot-Extendedandcohere-ai.
- Foundational Pre-Training Crawlers: Preserving
- Agent Protocol Headers: Emitting
X-Agent-Ready: true,X-RateLimit-Limit, andX-RateLimit-Remainingacross all public API routes to eliminate quota guesswork.
Benchmarking Agentic Experience (AX) and AI Visibility
To measure how effectively autonomous agents navigate zivisaiah.com, I test the site against two distinct evaluation layers:
- AI Visibility & Crawler Audits (e.g. Triple & Co AI Visibility Checker): Verifies that all 10 major AI answer engine and training crawlers have unrestricted access to root documentation and structured endpoints, ensuring a perfect 30/30 crawler accessibility score.
- Autonomous Agent Usability with Ora: Benchmarks multi-step autonomous journeys (such as Claude Code or custom delegates executing complex goals across the domain).
By pairing local webmcpgate CI tests (which evaluate manifest integrity, taxonomy adherence, and tool schemas) with external AI visibility audits and Ora AX scoring, the site maintains a continuous, regression-free bridge for the agentic web.
The Hard Lesson: Agent Readiness Requires CI/CD Gates
Building the initial WebMCP endpoints was only half the battle. The bigger challenge was keeping them working.
During my first week of testing, a routine CSS refactor accidentally broke an in-page JSON-LD tag. Two days later, a route change caused an endpoint schema mismatch. To human visitors, the site looked completely fine. To visiting AI agents, the site had broken.
This taught me a critical lesson: agent compatibility degrades rapidly unless you enforce it automatically in CI/CD.
To solve this permanently, I built an automated test harness and gatekeeper called webmcpgate.
The tool audits four dimensions of any web property:
- Machine Discovery (2.50 pts): Manifest tags,
/llms.txt, robots.txt, sitemaps. - Deterministic Semantics (2.50 pts): JSON-LD
@graphschema validation and landmark tags. - Tool Actionability (2.50 pts): Resource resolution, tool schemas, endpoint availability.
- WAF & Bot Resiliency (2.50 pts): Bot header pass rate and CORS compliance.
On my repository, every pull request and commit triggers the audit. If the overall readiness score drops below 9.45 / 10.0, GitHub Actions immediately fails the build:
- name: WebMCP & AI Agent Readiness Gate
  run: npx webmcpgate http://127.0.0.1:3000 --gate 9.45
By putting the gate directly into my deployment pipeline, I know that no visual update or frontend refactor can silently break my site’s machine interface.
Expanding to Full Production Regression Gates
As the site expanded, I realized that auditing WebMCP endpoints alone was not enough. A CSS adjustment could cause horizontal viewport blowout on mobile, an edited slug could break internal cross-links, or an unoptimized image could fail to render.
To guarantee complete production stability, I expanded my automated CI suite to include a Comprehensive Production Regression Gate (production-regression.test.ts):
- Mobile Viewport Integrity: Automatically scans all published essays to verify that no 3+ column tables exist to break mobile layouts, and enforces root horizontal scroll locks in CSS.
- Visual Asset Verification: Asserts that every in-body diagram exists on disk, contains no missing font glyphs, and is wrapped in a clickable zoom link.
- Link & Route Crawl: Crawls every internal hyperlink across all essays to ensure zero broken links or 404s.
- Machine-Discovery Parity: Validates that
llms.txtandllms-full.txtremain in perfect synchronization with published content on every build.
Audit Your Own Website
I packaged and open-sourced the test harness so any engineering team can evaluate their site in seconds.
You can run an instant audit against your domain right from your terminal:
npx webmcpgate https://yourwebsite.com
The tool generates an itemized scorecard across all four dimensions, highlights missing discovery tags, and checks whether your endpoints conform to valid JSON-Schema specs.
The full source code, CI integration examples, and documentation are available on GitHub: 👉 onegate-bot/webmcpgate on GitHub
The Road Ahead
We are entering an era where software interfaces will be used just as often by machines as by humans.
Building websites that only cater to human visual rendering is no longer enough. By exposing structured discovery, deterministic semantics, and schema-validated tools, we make the web faster, safer, and truly interoperable for the agentic future.